PredictSphere: The Predictive Intelligence Orchestration Engine
A Technical Case Study on Adaptive AI, Predictive Intelligence and Enterprise Decision Support (2022 - 2025)
Organisation: AI Technocrats
Product Lead: Atul Kumar
Domain: AI Innovation & Predictive Intelligence
Product inception: May 2022
Initial intelligent engine: August 2022
Initial engine substantially developed: November 2022
Continued platform evolution: 2023 - 2025
Executive Summary
PredictSphere is a Predictive Intelligence Orchestration Engine conceived to address persistent limitations in traditional enterprise analytics, including static predictive models, fragmented data ecosystems, limited explainability and the high cost of model adaptation.
The initiative began in May 2022 to develop an intelligent layer capable of coordinating predictive models, processing heterogeneous data, adapting to changing conditions and translating analytical outputs into actionable business insights.
The intelligent engine took shape in August 2022 and was substantially developed by November 2022. The broader platform vision continued beyond this initial milestone, with subsequent development focused on evaluation, integration, governance, operational refinement and expanded predictive capabilities through 2025.
The architectural approach combines meta-learning, reinforcement learning, natural-language task interpretation, probabilistic forecasting and an explainability layer referred to as the Insight Fabric. A feedback loop connects model outputs with observed outcomes to support evaluation and controlled improvement.
The original product case study reports predictive accuracy of 88–94%, an estimated direct business impact exceeding $4.8 million, a 62–72% reduction in time to insight and improvements in user engagement and operational decision support. These figures are presented as reported product outcomes and require supporting evaluation records for independent verification.
PredictSphere's central objective is to move enterprise predictive analytics beyond isolated forecasting models toward a coordinated, adaptive and explainable intelligence system.
1. Business Context and Problem Statement
1.1 The limitations of traditional predictive analytics
Enterprises increasingly depend on predictive models to forecast demand, assess risk, identify anomalies and support operational decisions. However, conventional predictive systems often struggle when their operating environments change.
Models trained on historical data can deteriorate as new observations differ from their training distributions. Data is frequently distributed across ERP systems, CRM platforms, IoT infrastructure, external APIs and legacy data warehouses. Inconsistent schemas and fragmented pipelines complicate the process of producing a unified analytical view. Another challenge is explainability. A prediction may be statistically useful but difficult for business users to interpret. When decision-makers cannot understand the reasoning behind a recommendation, they may disregard the output or revert to manual processes.
Model retraining also introduces operational costs. New datasets, changing business requirements and emerging patterns can require repeated engineering, validation and computing work.
These challenges established the need for an architecture that could coordinate predictive models, integrate data, communicate uncertainty and support adaptation without treating every new requirement as an isolated machine-learning product.
1.2 Sector-specific challenges
Finance: Fraud patterns change rapidly, while risk models must respond to evolving behaviour and regulatory requirements. Systems must balance the detection of genuine risks with the cost of false alarms.
Healthcare: Readmission forecasting and resource planning depend on changing patient conditions, staffing levels and operational constraints. Predictions must be interpretable and used within appropriate clinical oversight.
Logistics and commerce: Demand volatility, supplier delays and transportation disruptions create uncertainty in inventory planning and fulfilment. Forecasting systems must support scenario analysis rather than rely solely on historical averages.
1.3 Product objective
- PredictSphere was conceived to provide a common predictive intelligence layer with five principal objectives:
- Harmonise heterogeneous enterprise data.
- Coordinate suitable predictive models for different analytical tasks.
- Support rapid adaptation to new domains and changing conditions.
- Provide understandable explanations and uncertainty information.
- Use observed outcomes to inform the controlled model and policy improvement.
The objective was not simply to generate a forecast. It was to connect data, prediction, explanation and feedback within a unified analytical workflow.
2. Product Development Journey
The development journey is divided into the initial engine milestone and the subsequent evolution of the broader platform.
May 2022: Product inception
The product began with the identification of limitations in conventional predictive analytics and the definition of a more adaptive architecture. Early work focused on problem definition, requirements, feasibility and the relationship between data integration, model adaptation and business decision support.
June–July 2022: Architecture and foundation
The next stage focused on the conceptual architecture for data ingestion, model coordination, predictive processing and feedback. The design emphasised modularity so that new data sources and analytical techniques could be incorporated without redesigning the entire system.
August 2022: Intelligent engine development
August marked a key milestone in the development of the intelligent engine. The core direction was to coordinate predictive models and supporting intelligence components within a common framework. This included the intended integration of data harmonisation, adaptive learning, forecasting and explanation capabilities.
September–November 2022: Integration and initial functional maturity
The development focus shifted toward integration and refinement of the initial engine. The principal objective was to bring the architecture's core components into a coherent workflow and establish a foundation for evaluation and subsequent extension. By November 2022, the initial engine was substantially developed. This milestone marked the initial implementation's maturity, not the completion of every feature, enterprise integration, or deployment objective.
2023: Evaluation and platform refinement
The subsequent development scope included testing, refinement, feedback mechanisms, explainability and governance. The broader objective was to evaluate the engine's usefulness across predictive workflows and improve the relationship between model outputs and operational decisions.
2024–2025: Continued evolution
The longer-term platform scope included further integration, optimisation, operational refinement and exploration of expanded capabilities. The original case study describes continued work involving adaptation, supply-chain scenarios and future extensions. Specific deployments, completed milestones and quantitative outcomes during this period should be supported by product records.
3. Solution Overview
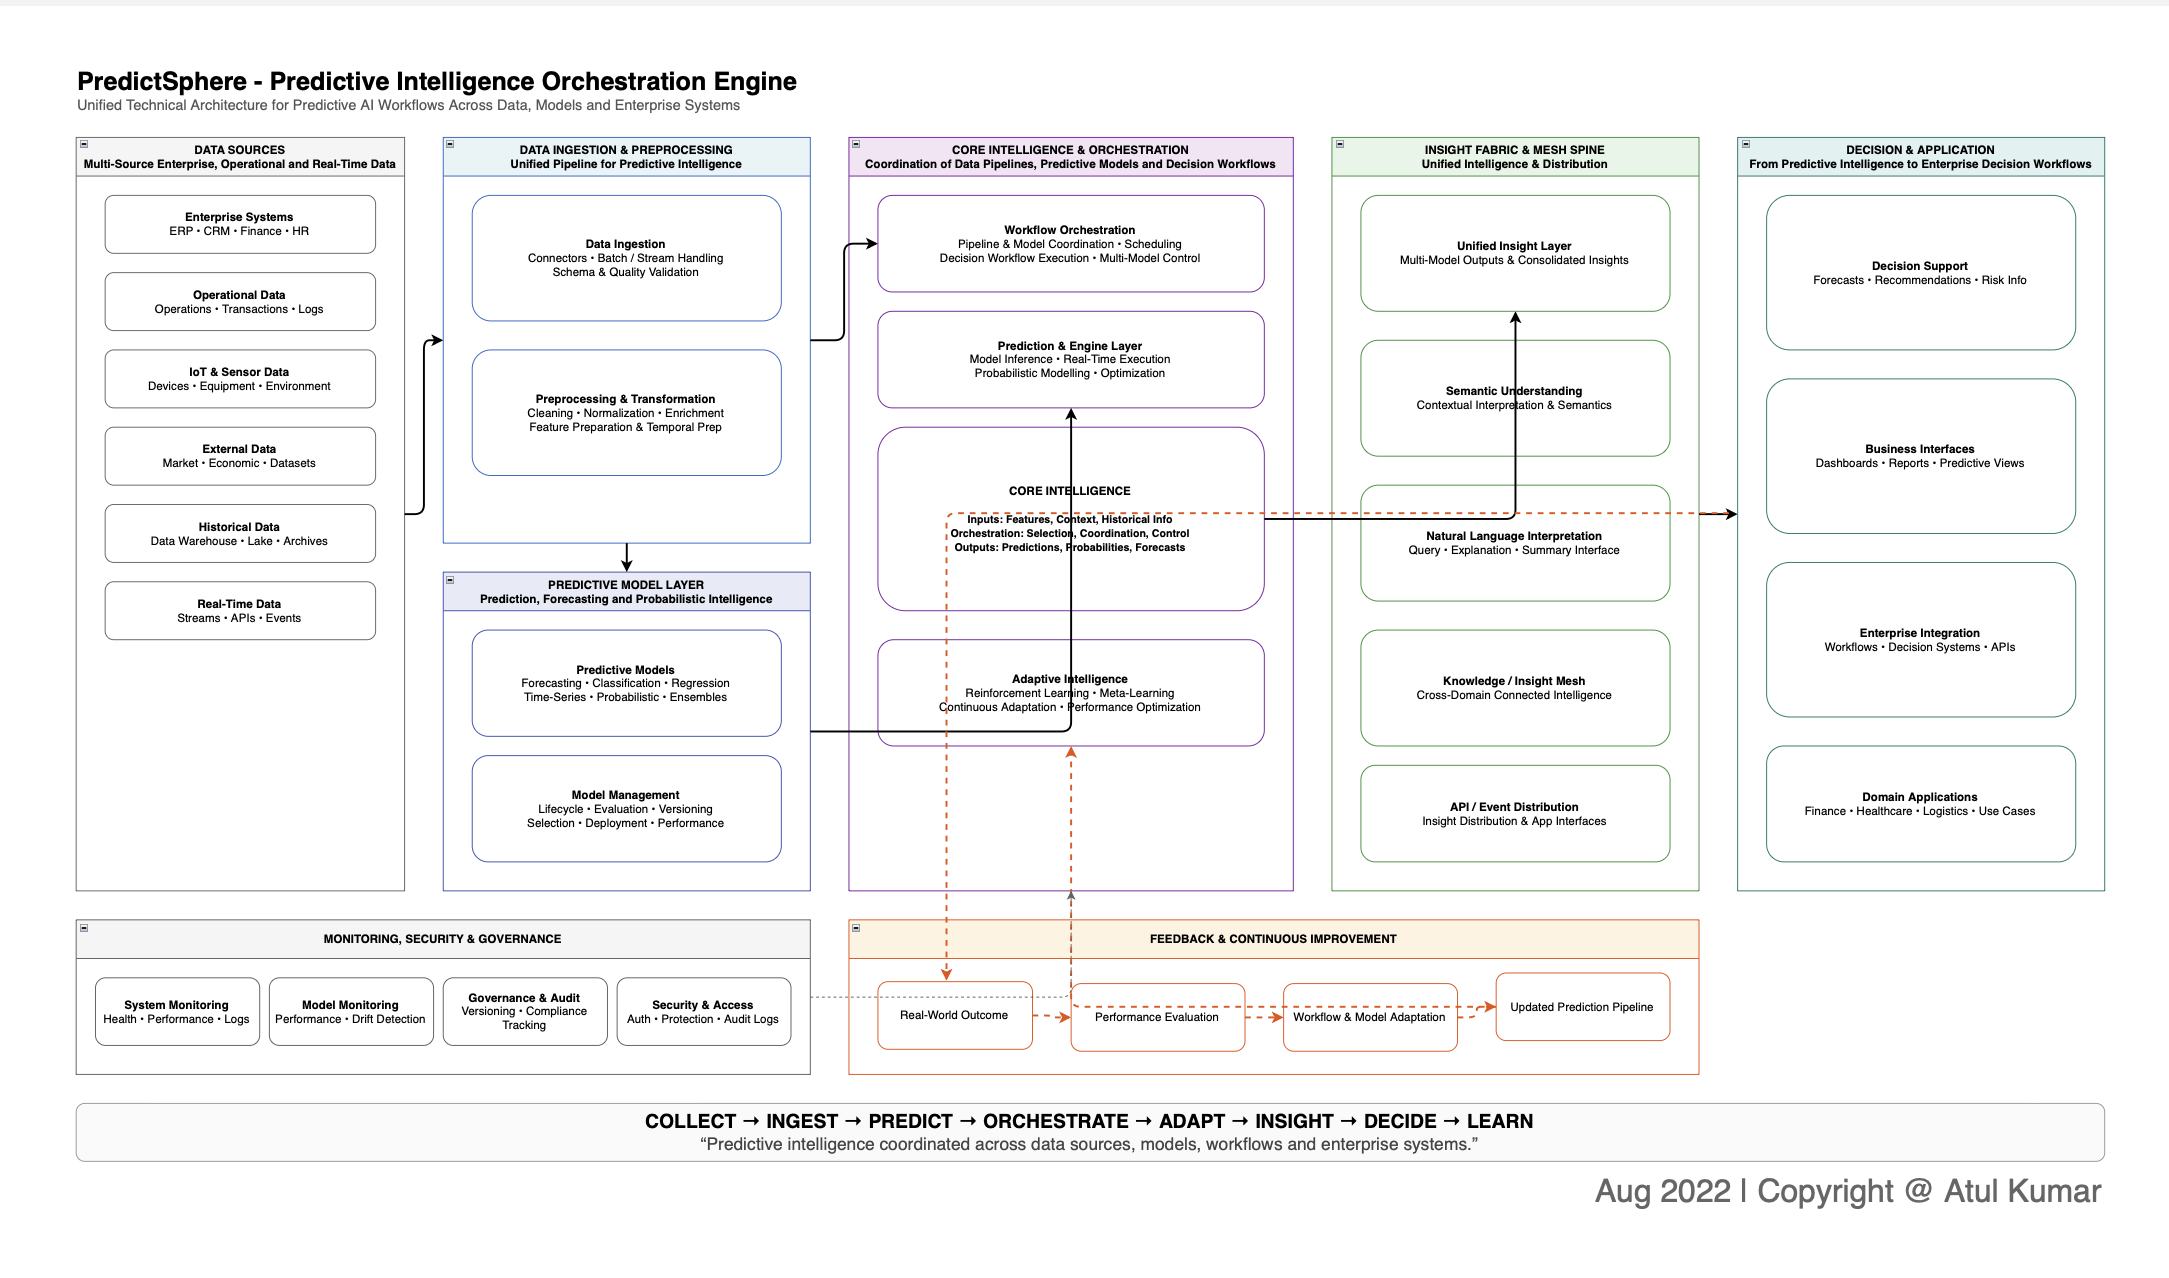
PredictSphere was designed as an orchestration layer above conventional machine-learning pipelines.
Instead of requiring a single model to address every predictive problem, the architecture coordinates multiple analytical capabilities according to the task, available data and operational requirements.
The solution consists of four interconnected layers:
- Data ingestion and harmonisation.
- Core intelligence and model coordination.
- Prediction and explainability.
- Feedback and adaptation.
These layers form a workflow in which data is prepared, models generate predictions, results are explained and observed outcomes can inform subsequent evaluation.
4. Technical Architecture
4.1 Data ingestion and harmonisation
The data layer is responsible for integrating heterogeneous information and preparing it for predictive processing. The original architecture describes:
- Real-time ingestion using Apache Kafka.
- Batch processing using Apache Spark.
- Schema interpretation using large language models and rule-based normalisers.
- Automated data-quality checks, anomaly detection, imputation and drift alerts.
- Enrichment with external signals, including weather and economic indicators, using embeddings.
The purpose of this layer is to reduce inconsistencies between source systems and establish a more reliable foundation for downstream models.
Data quality remains a critical dependency. Missing values, delayed updates, inconsistent identifiers and distribution changes can affect the quality of the resulting predictions.
4.2 Meta-learning framework
Meta-learning explores how a model can use knowledge acquired from previous tasks to adapt more efficiently to a new task. PredictSphere's described approach uses a Model-Agnostic Meta-Learning (MAML)-inspired framework with task-agnostic optimisation.
The conceptual process includes an inner loop for task-specific adaptation and an outer loop for optimising the model's ability to adapt across tasks. This approach is intended to reduce the amount of new training data and engineering work required when moving between related predictive domains. The original case study reports adaptation using fewer than 100 examples for new domains. This figure should be interpreted as a reported product claim; a reproducible benchmark would need to identify the datasets, task definitions, evaluation conditions and performance thresholds.
4.3 Reinforcement-learning component
The reinforcement-learning component is intended to improve decisions through feedback from observed outcomes. The original architecture identifies Proximal Policy Optimisation (PPO) and custom multi-objective reward functions. The described reward objectives include:
- Predictive accuracy.
- Business utility, such as cost savings or risk reduction.
- Operational stability.
The original case study states that feedback from production outcomes was used to update policies weekly. This design introduces a feedback mechanism between operational results and subsequent optimisation. It also requires careful reward design: optimising one objective in isolation can create undesirable trade-offs elsewhere. Appropriate evaluation, constraints and monitoring are necessary to ensure that policy updates remain aligned with the intended business objective.
4.4 Natural-language interpretation
PredictSphere's natural-language interface is intended to make predictive analysis accessible to users who do not interact directly with machine-learning tools.
For example, a supply planner might ask:
“Simulate the impact of a 20% supplier delay on second-quarter inventory.”
The system is intended to translate this request into a structured task involving forecasting and scenario analysis. A workflow may involve retrieving relevant inventory data, defining assumptions, generating a forecast and presenting the potential implications. The usefulness of the output depends on data availability, the validity of assumptions and the suitability of the selected analytical methods.
4.5 Prediction engine
The original case study describes an ensemble-oriented prediction engine incorporating:
- Bayesian neural networks.
- Gaussian processes.
- Transformer-based forecasting models.
- Anomaly and pattern detection.
- Causal inference and counterfactual analysis.
Different models are suited to different data characteristics and prediction objectives. The orchestration layer is intended to support the selection and coordination of appropriate methods rather than assume that a single model is optimal for every task.
4.6 Insight Fabric: Explainability and transparency
The Insight Fabric is the explainability layer designed to make predictions easier to interpret.
Its described capabilities include hierarchical explanations, supporting evidence, feature attribution and confidence intervals.
The explanation process is organised around three levels:
- Summary: The main forecast or recommendation.
- Supporting evidence: Relevant variables and patterns contributing to the output.
- Detailed analysis: Uncertainty information and deeper technical context.
The original case study references DoWhy and counterfactual analysis for causal questions, alongside SHAP/LIME-style feature attribution.
These methods serve different purposes. Feature attribution can indicate which inputs influenced a model's output, while causal analysis requires additional assumptions and evidence. Neither should be treated as an automatic guarantee that every explanation is causally valid.
4.7 Feedback and adaptation loop
The feedback loop connects predictive outputs with subsequent evaluation.
The described workflow is:
- Generate a prediction or recommendation.
- Record the model output and relevant input conditions.
- Capture the outcome when it becomes available.
- Calculate the relevant reward or evaluation metric.
- Monitor changes in model performance.
- Trigger appropriate adaptation, recalibration or policy updates.
- Validate the updated system before broader use.
This design is intended to help the platform respond to changing conditions while maintaining control over model changes.
5. Deployment Approach and Governance
A predictive intelligence platform requires more than strong model performance. It must also operate within clear controls, permissions and evaluation procedures.
The original case study describes a phased deployment approach.
Sandbox and shadow mode
Predictions are generated and recorded without directly controlling operational decisions. This allows outputs to be evaluated against actual outcomes and existing processes.
Human-in-the-loop decision support
Selected workflows use predictive recommendations while authorised personnel retain decision-making authority. This phase allows teams to assess the usefulness of the recommendations, identify failure modes and improve the quality of the workflow.
Approved autonomous workflows
Automation may be introduced for specifically approved workflows once suitable validation and governance requirements have been satisfied.
The original case study describes this as a progression toward partial autonomy. The actual deployment status of individual workflows should be established from operational records.
Governance and safeguards
The architecture describes several governance measures:
- Human veto and review.
- Audit trails.
- Differential privacy and federated elements for selected sensitive-data scenarios.
- Weekly drift and performance dashboards.
- Controlled updates to models and policies.
These measures are important because adaptation can introduce new failure modes. An updated model may perform differently from its predecessor, and a policy that improves one metric may negatively affect another. The implementation and effectiveness of each safeguard should be assessed separately for each deployment.
6. Industry Applications
6.1 Finance: Fraud detection and credit risk
PredictSphere's financial use case focuses on detecting changing fraud patterns and supporting risk analysis.
The described approach combines predictive modelling, adaptation and outcome-based optimisation. Meta-learning can be explored for changing patterns across related tasks, while reinforcement learning can support decision optimisation under explicitly defined objectives. Explainability can help investigators understand the factors associated with a risk alert and prioritise further investigation. The principal business objective is to improve risk visibility while balancing detection performance, false alarms and operational cost.
6.2 Healthcare: Readmission and resource forecasting
The healthcare use case focuses on estimating readmission risk and supporting resource planning. Predictive models can help identify higher-risk cohorts and estimate demand for staffing and other resources. Causal analysis can be used to investigate potential intervention scenarios, provided that the data and assumptions support the analysis. Natural-language interaction is intended to make insights more accessible to healthcare professionals and administrators. Such systems must remain subject to appropriate privacy protections, clinical oversight and validation before influencing consequential decisions.
6.3 Logistics: Demand and supply-chain optimisation
The logistics use case focuses on demand forecasting, inventory planning and supply-chain disruption analysis. Probabilistic forecasts and scenario simulations can help planners understand how changes in demand, supplier timing or transportation conditions may affect inventory availability. The intended benefits include better visibility into supply-chain risks, fewer avoidable inventory imbalances and improved planning under uncertainty.
7. Reported Results and Business Impact
The original PredictSphere case study reports several quantitative outcomes. The figures below preserve the published claims; they should not be interpreted as independently audited results without supporting evidence.
7.1 Predictive accuracy
| Domain | Reported accuracy |
| Overall predictive scenarios | 88–94% |
| Finance | 92–94% |
| Healthcare | 88–91% |
| Logistics | 89–93% |
| Legacy baseline | 68–78% |
The original article presents these figures as evidence of improved predictive performance. For rigorous evaluation, accuracy should be accompanied by the dataset, prediction target, test period, baseline definition and relevant metrics. For imbalanced problems, precision, recall and calibration may be more informative than accuracy alone.
7.2 Time to insight
The original case study reports a reduction in time to insight from 3–14 days to 2–24 hours, with an average reduction of approximately 68%. The intended benefit is a more integrated workflow connecting data preparation, predictive analysis and explanation. The reported metric should distinguish model execution time from the complete business process, including data preparation, review and approval.
7.3 Reported financial impact
| Application | Reported outcome | Estimated financial impact |
| Fraud detection | 38% fewer undetected incidents | Approximately $1.9 million |
| Healthcare | 31% reduction in readmissions in the high-risk cohort | Approximately $1.4 million in avoided costs |
| Inventory optimisation | 21% lower holding costs and 17% fewer stockouts | Approximately $1.5 million |
| Total | Estimated direct business impact | $4.8 million+ |
The original case study also reports a payback period of less than 12 months. These figures should be treated as reported estimates until their calculation methods and underlying records are available. Financial reporting should distinguish realised savings from avoided costs, produced benefits and revenue protection.
7.4 Adoption and operational efficiency
The original article reports:
- 87% active user engagement in its headline metrics.
- A 42% reduction in manual overrides is attributed to explainability.
- Four to seven hours saved per week per analyst or decision-maker.
- Less than a 5% accuracy drop during adaptation to novel conditions, compared with 20–35% in static systems.
The article also reports a temporary performance decline of 3–6% during 2024 supply disruptions. These figures indicate the types of operational benefits the product sought to demonstrate. Their interpretation requires clear metric definitions, comparison periods and evidence connecting the changes to the platform.
8. Engineering Challenges and Lessons Learned
Data quality
Heterogeneous data sources introduced challenges involving incomplete records, inconsistent formats and changing distributions. The engineering lesson is that predictive quality depends on reliable data preparation, monitoring and validation, not only on model selection.
Explainability
Detailed explanations can overwhelm users, while oversimplified explanations can omit important limitations. The Insight Fabric approach addresses this by providing a high-level summary with the option to inspect supporting evidence and uncertainty.
Reward design
Reinforcement-learning systems require carefully designed objectives. A reward that focuses only on accuracy or cost savings may produce undesirable trade-offs in other business objectives. Multiple objectives, explicit constraints and ongoing evaluation are necessary to maintain the intended behaviour.
Adoption and change management
Users need to understand what a prediction means, how much confidence to place in it and when human review is necessary. Demonstrations, documentation, training and feedback channels can help integrate predictive tools into existing decision-making processes.
Scaling and continued reliability
The expansion of a predictive platform introduces new dependencies involving data availability, model versions, infrastructure and operational workflows. Version control, regression testing, monitoring and controlled releases are useful engineering practices for maintaining reliability as the platform evolves.
9. Strategic Outlook and Future Scope
The original case study identifies three principal areas for future development.
Multimodal inputs
The platform's future scope includes incorporating images and unstructured documents alongside structured data, where appropriate models and evaluation methods are available.
Agentic extensions
Agentic capabilities could coordinate analytical tools and produce proactive recommendations based on forecast outcomes. Such capabilities would require clearly defined permissions, bounded execution, auditability and appropriate human oversight.
Cross-organisation federation
Federated approaches could support collaborative learning across distributed environments where sharing raw data is restricted or impractical. This direction introduces additional requirements involving privacy, model compatibility, governance and validation across different organisations. The implementation status of these capabilities should be distinguished from the initial engine and from features demonstrated in a specific deployment.
10. Conclusion
PredictSphere was conceived to address a fundamental limitation in enterprise predictive analytics: the gap between generating a prediction and operating a reliable, explainable intelligence system. Beginning in May 2022, the initiative progressed toward an intelligent engine that was substantially developed by November 2022. The broader platform subsequently continued through 2023–2025, with a focus on refinement, evaluation, integration and expanded capabilities. Its architectural direction brings together heterogeneous data processing, meta-learning, reinforcement learning, predictive model orchestration, natural-language interaction and the Insight Fabric. The product illustrates an important engineering principle: predictive intelligence depends not only on the model, but also on the quality of its inputs, the reliability of its evaluation, the transparency of its outputs and the controls governing its adaptation.
The longer-term ambition is to support enterprise systems that can interpret changing conditions, evaluate alternative scenarios and improve decision support through measured feedback.
PredictSphere's central vision is to transform predictive analytics from an isolated modelling activity into a coordinated intelligence capability - one that connects data, forecasts, explanations and operational learning within a common architecture.
Product Leadership
Atul Kumar
Product Lead - PredictSphere
AI Innovation & Predictive Intelligence
AI Technocrats